The building as it is, objects as boxes: second version.
Second version of the building-and-objects reconstruction, after review. Things that stand on their own keep their box however small; only small things crowded together are grouped or left out; thin soft hangings against walls (curtains, blinds) are left out. Things in rows or along a wall take one direction, stated by the agent from the photographs. The host no longer opens walls or adds spaces by itself: it lists where predicted depth suggests an opening, and the agent decides from the photographs. Context photographs for video generation are now chosen on the reconstruction point cloud, independent of how the proxy is drawn.
Point cloud, boxes and proxy video
The latest reconstruction of each scene: its predicted point cloud with the boxes and building parts of the exported scene (drag to orbit, scroll to zoom, pick an object from the list), and the proxy rendered along the input cameras in capture order.
Scenes used during development
Rotunda museum
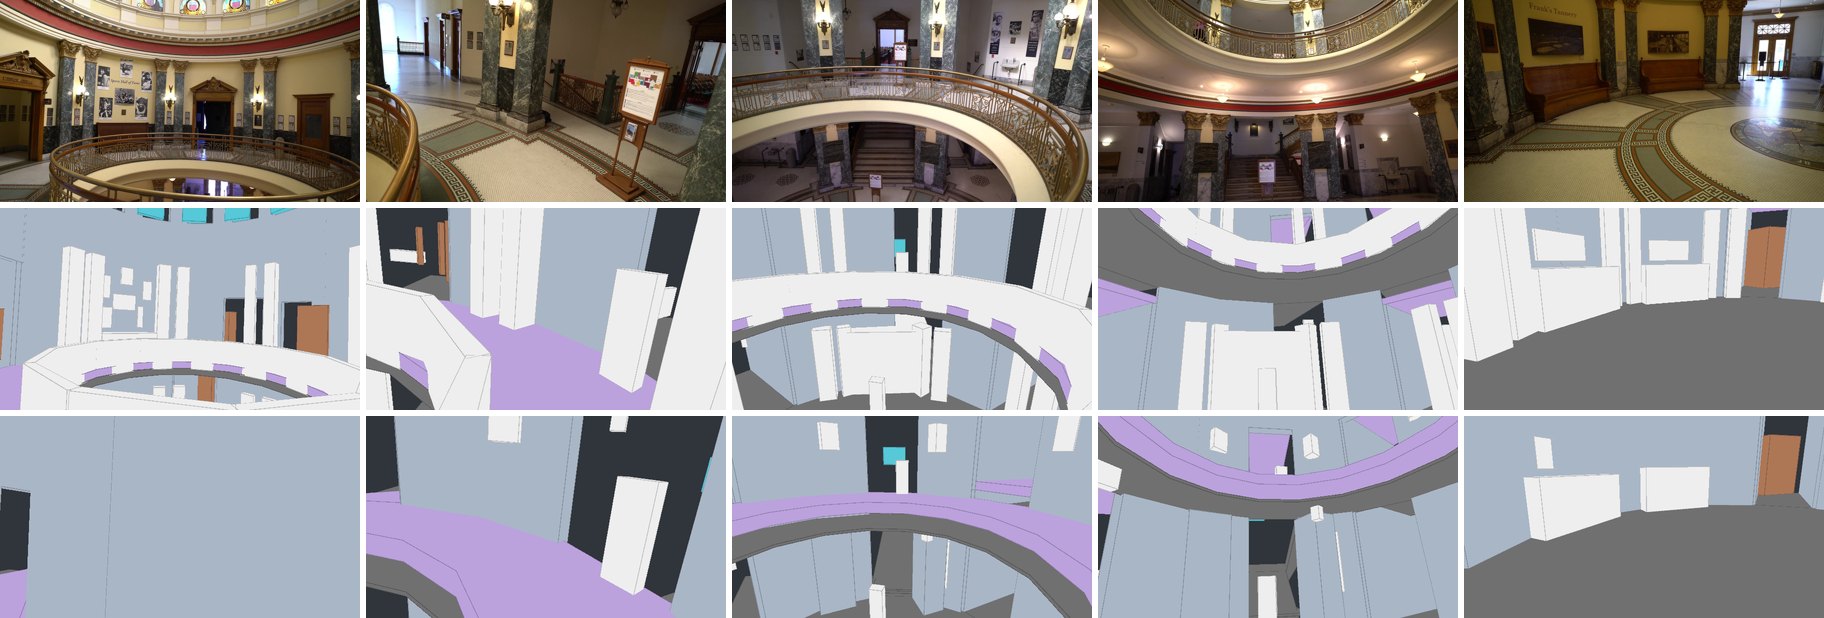
Top: input photographs. Middle: proxy of the previous release. Bottom: proxy of this release, from the same cameras.
Mission church
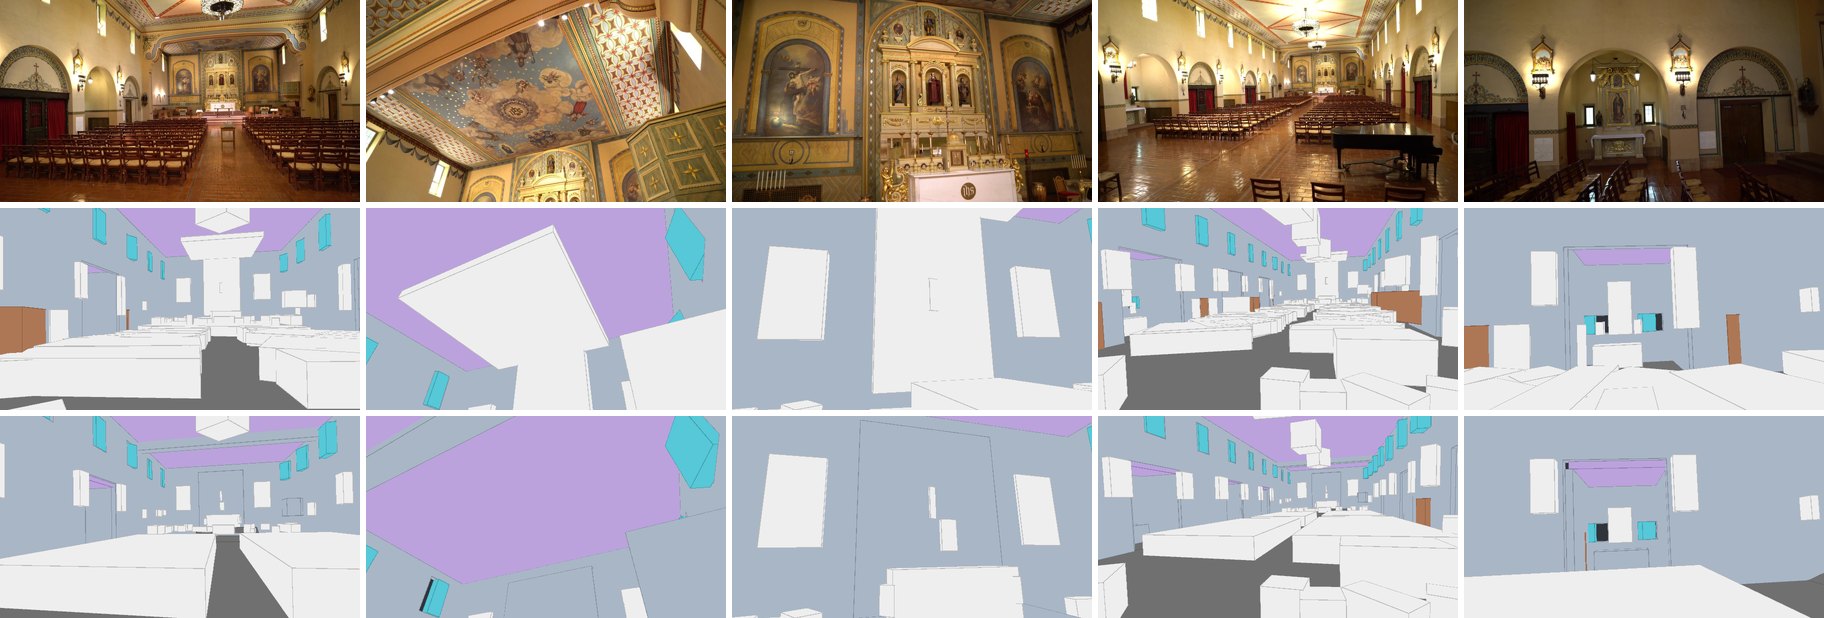
Top: input photographs. Middle: proxy of the previous release. Bottom: proxy of this release, from the same cameras.
Bedroom (ground truth)
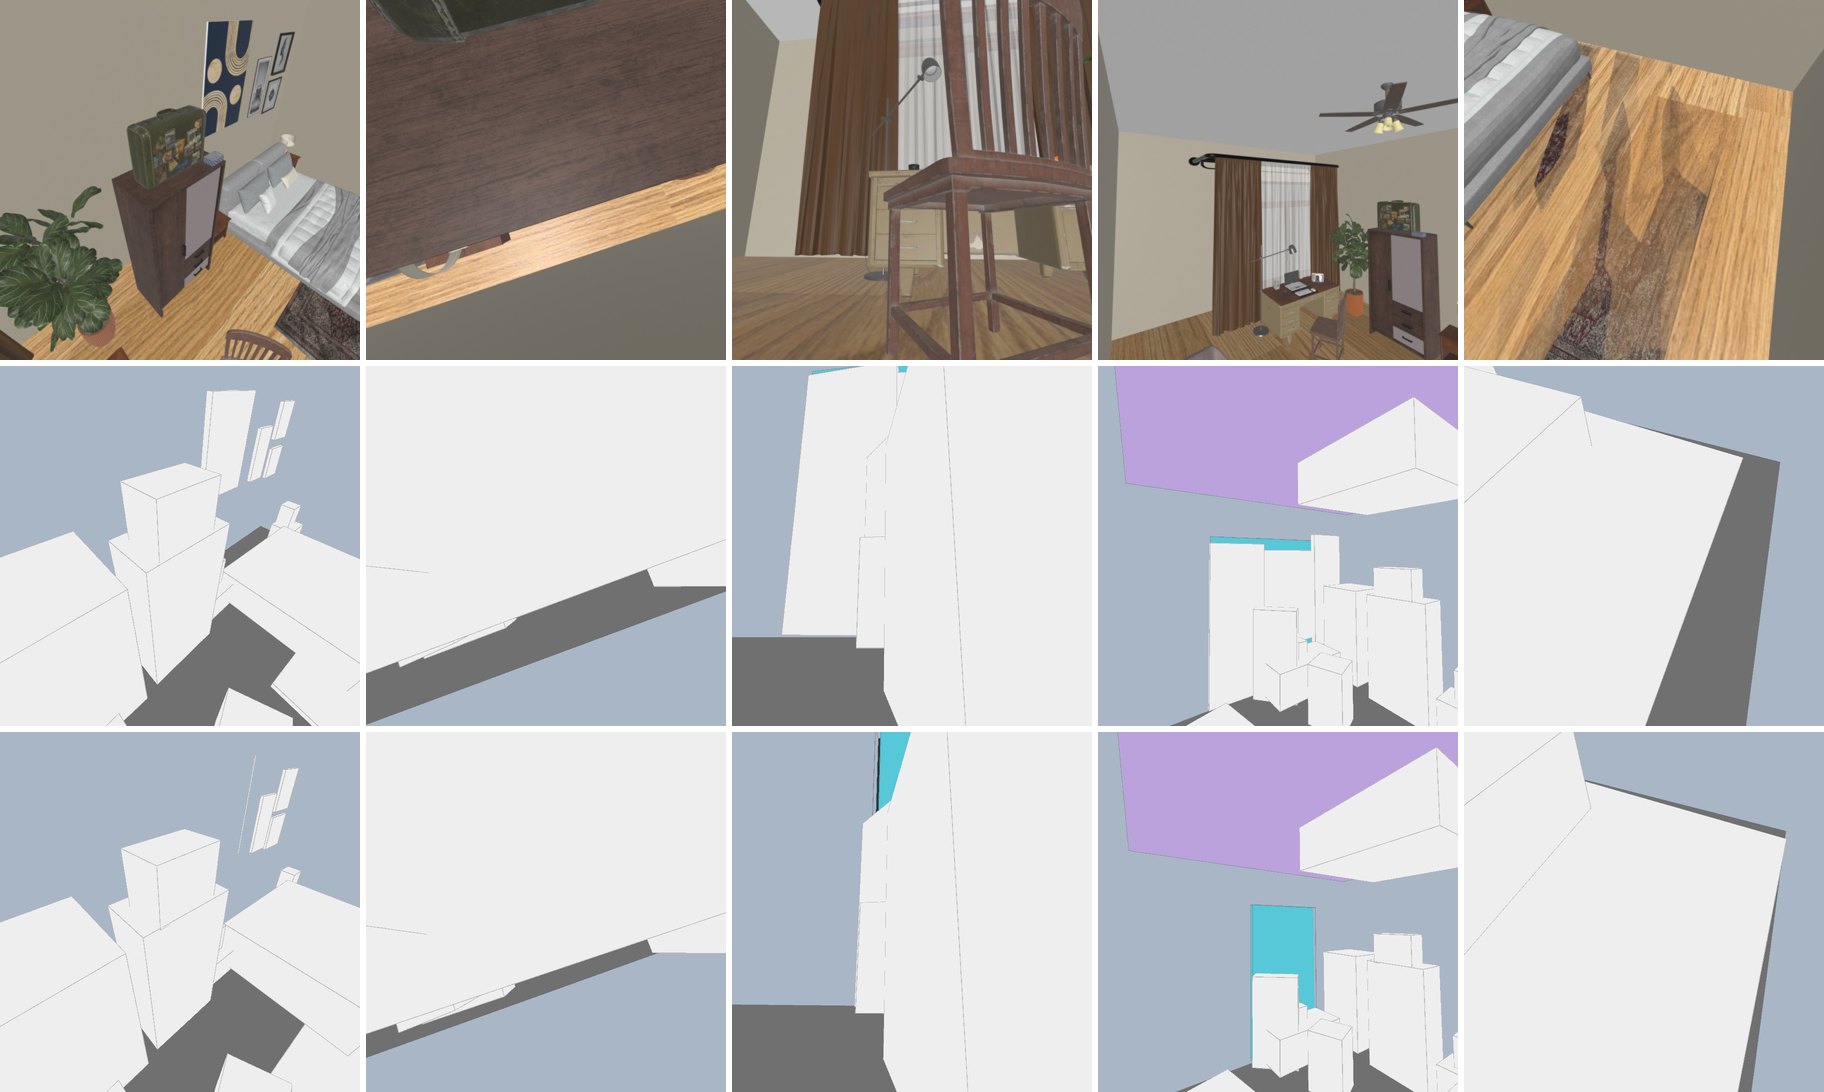
Top: input photographs. Middle: proxy of the previous release. Bottom: proxy of this release, from the same cameras.
Apartment (not used during development)
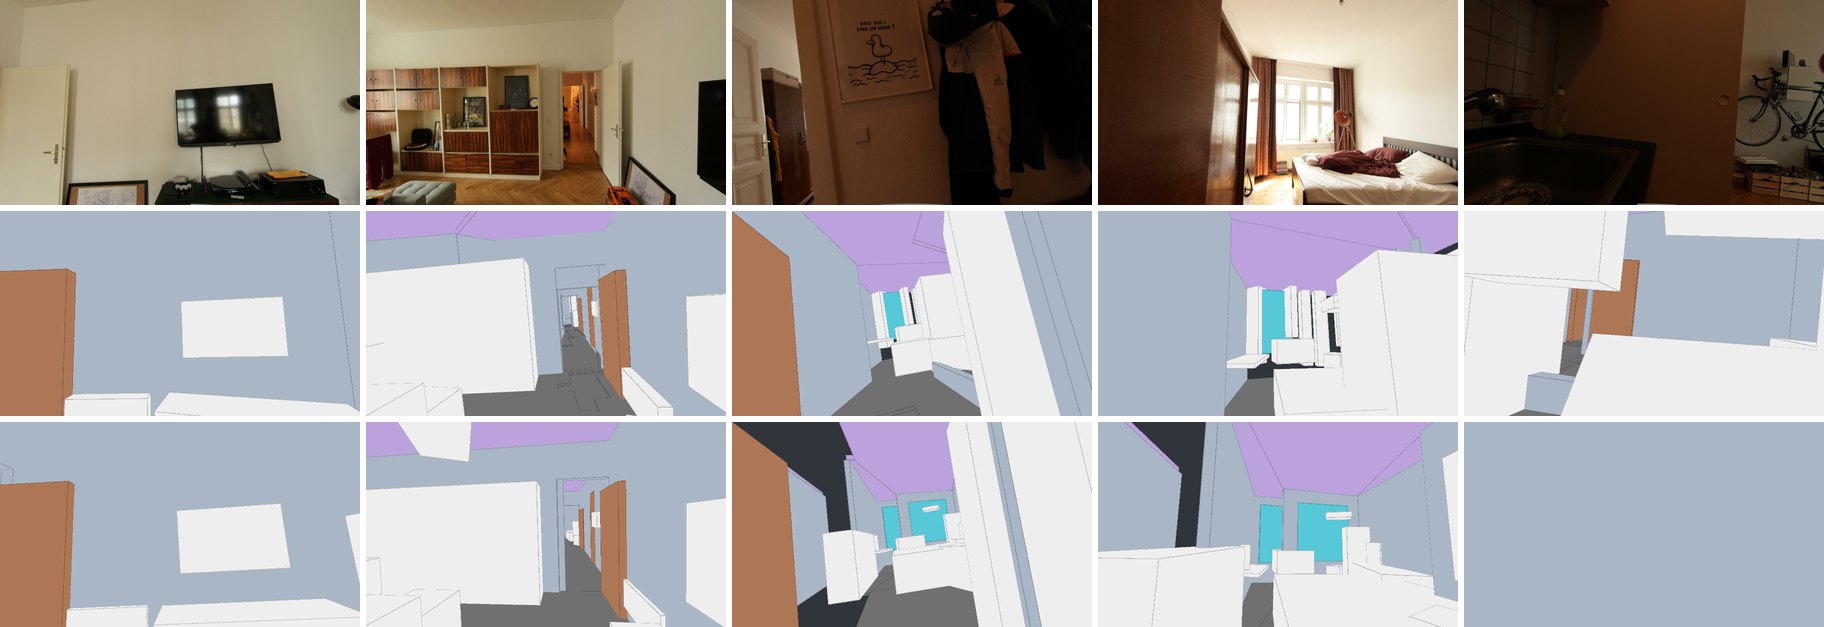
Top: input photographs. Middle: proxy of the previous release. Bottom: proxy of this release, from the same cameras.
Scenes
Each picture row: input photographs, then the proxy of the previous release (the apartment: of the first version of this work), then the proxy of this version, from the same cameras.
Accuracy and time
Ground truth: the previous release six runs on the meeting room and five on the bedroom, this version three each. Held-out video: twelve stretches of input photographs taken out, the camera follows them and the generated video is compared with the photographs; each version reconstructed twice, contexts chosen the same way for both, means per scene, interval by bootstrap over the six scenes. Wall clock of this version was measured in one batch of twenty runs, without the previous release in the same batch.
| measure | previous release | this release | note |
|---|---|---|---|
| Meeting room: mIoU | 0.610 | 0.647 | difference +0.037 (95% interval +0.024 to +0.048) |
| Meeting room: recall at IoU 0.5 | 0.81 | 0.90 | |
| Bedroom: mIoU | 0.673 | 0.696 | difference +0.022 (95% interval +0.017 to +0.027) |
| Bedroom: recall at IoU 0.5 | 0.92 | 1.00 | |
| Video on photographs left out: PSNR | 15.56 dB | 15.29 dB | difference -0.27 dB (95% interval -0.88 to +0.25) |
| Video on photographs left out: SSIM / LPIPS | 0.553 / 0.354 | 0.550 / 0.356 | |
| Video: spread between two reconstructions of one scene | 1.04 dB | 0.59 dB | |
| Time, bedroom | 360 s | 582 s | not paired; editing sessions are longer |
| Time, office | 433 s | 571 s | not paired |
| Time, Mont-Saint-Michel | 495 s | 688 s | not paired |
| Time, lighthouse | 499 s | 713 s | not paired |
| Time, meeting room | 463 s | 451 s | not paired |
| Object boxes: church / museum | 180 / 111 | 96 / 52 | curtains in the church 27 to 0 |
| Object boxes: apartment / bedroom | 79 / 24 | 73 / 21 | curtains 10 to 0 and 3 to 0; pictures kept |
What changed
- A thing that stands on its own and can be made out in the views keeps its own box, however small (a picture, a lamp, a fan). Small things crowded together become one box for the group or are left out; the larger the place, the more of its contents form such groups. Each candidate carries a crowd number: how many other candidates stand close around it.
- Thin soft things that hang close to a wall, a window or a ceiling are left out unless they stand clear of the wall and fill a large part of the views.
- Things in rows or a grid, and furniture along one wall, share one direction: the agent states it from the photographs (one member is the reference, the others follow it exactly).
- The host still fits floors, ceilings and walls to the predicted depth and cuts back building parts, but it no longer opens walls, opens floors or adds spaces on its own: it lists those places with their frames, and the agent decides from the photographs.
- Boxes that cover a quarter of a view that sees past them are listed for the agent again.
- Context photographs for video generation are chosen on the depth each photograph recorded and on the reconstruction point cloud, so the choice no longer changes with how the proxy is drawn.